
Autonomous IT operations let systems detect, decide, act, and verify within policy guardrails instead of waiting for a human to triage every alert. The outcome that matters: less manual firefighting, faster incident resolution, and infrastructure that fixes known problems before anyone opens a ticket. None of this removes people from the loop entirely. It just moves them from clicking buttons to setting the rules the system follows.
TL;DR:
- Autonomous IT operations combine detection, decision, action, and verification under policy guardrails, moving beyond simple automation and AIOps.
- A successful pilot should start with low-risk, high-volume use cases like certificate expiry or disk cleanup and measure baseline metrics for at least two to four weeks.
- Critical layers include observability, AIOps, automation engines, and integrations, with vendor openness and API accessibility essential for effective system connectivity.
- Governance controls such as role-based access, audit logging, staging, and ongoing monitoring are vital to prevent untrusted autonomous actions.
- A staged rollout involves initial recommendations, then human approvals, followed by auto-run policies with rollback capabilities, before full autonomy is implemented.
Table of Contents
- What Autonomous IT Operations Means (And Where It Sits Next to Automation and AIOps)
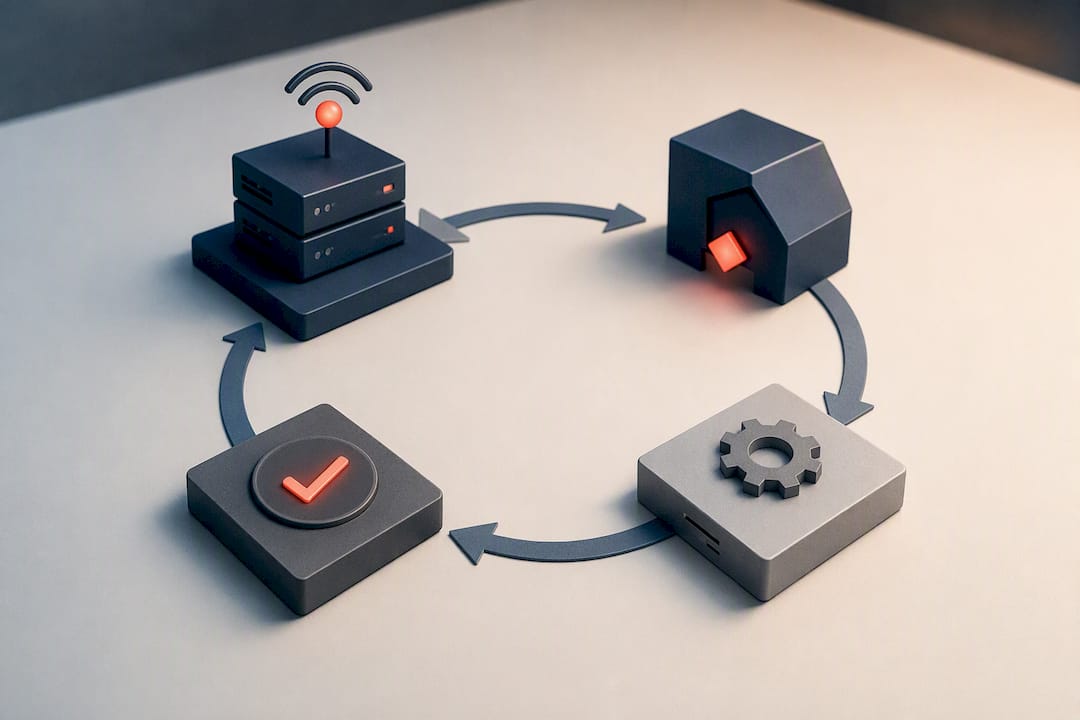
- The Detect, Decide, Act, Verify Loop Explained
- What to Measure Before You Call a Pilot Successful
- The Stack You Need Before Autonomy Works
- A Staged Rollout Plan That Won't Blow Up Your Environment
- Governance Isn't Optional at Any Stage of Autonomy
- How Mindpodtech Approaches Autonomous IT in Practice
- An Implementer's Take on What Actually Slows Teams Down
- Start With a Free Assessment, Not a Full Rebuild
- Sources
- FAQ
What Autonomous IT Operations Means (And Where It Sits Next to Automation and AIOps)
The terms get used interchangeably, and that's a mistake. Automation runs a fixed script when triggered. AIOps analyzes telemetry with machine learning to find patterns a human would miss. Autonomous IT ties both together into a closed loop that connects detection, decision, action, and verification under policy guardrails, so the system doesn't just flag a problem, it resolves it and confirms the fix held.
Think of it as a maturity ladder, not a light switch. Most organizations start at recommendations, where the system tells a human what it would do. The middle stage is semi-automated action, where low-risk fixes execute automatically but higher-stakes ones wait for sign-off. The top stage is closed-loop remediation, where approved runbooks run without a human in the moment, though a human still owns the policy that authorized them.
Common entry points for this ladder include:
- Incident triage that correlates alerts and assigns priority before a technician even looks at the queue
- Runbook execution for known, repeatable fixes like restarting a hung service or clearing a disk
- Auto-scaling that adjusts compute capacity against real demand instead of static thresholds
- Certificate and compliance remediation that catches expiring certs or config drift before it becomes an outage
Jumping straight to full autonomy on a system you don't fully understand is how you automate a bad decision at scale. The ladder exists for a reason.
The Detect, Decide, Act, Verify Loop Explained
Every autonomous action runs through four stages, and skipping any one of them is where most failures come from.
- Detect. Telemetry from metrics, logs, traces, and synthetic experience monitoring feeds into a correlation layer that separates real signal from noise. This is also where AIOps earns its place in the stack, using machine learning to automate event correlation, anomaly detection, and causality determination across systems that would otherwise generate thousands of disconnected alerts.
- Decide. The correlated signal gets checked against policy: is this within an approved SLO, does the fix fall under a cost cap, is there an approved runbook for this exact failure pattern? If not, the decision escalates to a person instead of forcing an action.
- Act. The automation engine executes the runbook, whether that's restarting a service, rerouting traffic, or scaling a resource pool. Anything outside the pre-approved scope waits for a human approval gate.
- Verify. The system confirms the fix actually worked and didn't create a new problem elsewhere, with rollback ready if verification fails.
Root cause analysis and service impact mapping happen inside the decide stage, and they're what separate a system that reacts to symptoms from one that understands which upstream service actually broke.
Pro Tip: Start your verification step with the simplest possible check, like confirming a service responds on its health endpoint, before layering in more complex validation. Teams that try to build perfect verification logic on day one usually end up shipping none at all.
What to Measure Before You Call a Pilot Successful
The metrics that matter here are the same ones your operations team already tracks, just with a different baseline to compare against. Mean time to detect and mean time to resolve (MTTR) are the obvious ones, but alert noise reduction often has the bigger visible impact on team morale, because engineers stop drowning in duplicate pages for the same underlying failure.
By the numbers: The metrics that translate cleanest to a leadership conversation are service availability against your defined SLOs and operational cost per incident, because both connect directly to revenue protection and staffing costs rather than staying stuck in engineering jargon.
Set a baseline before you automate anything. Track these for at least two to four weeks pre-pilot:
- Mean time to detect and mean time to resolve for your target incident type
- Volume of duplicate or low-value alerts hitting the on-call rotation
- Service availability against existing SLOs
- Engineer hours spent on the specific remediation task you're about to automate
Once the pilot runs, compare against that baseline instead of an industry benchmark you can't verify. A 30% MTTR reduction on your own historical data is a defensible number in a board conversation. A vendor's marketing claim about "industry-leading" results is not.
The Stack You Need Before Autonomy Works
Autonomous operations aren't one product. They're a set of layers that have to talk to each other cleanly, and the integration quality matters more than any single tool's feature list.
- Observability gives you unified telemetry and service mapping, so the system knows which components depend on which, not just that something threw an error.
- AIOps sits on top of that telemetry for correlation and inference, turning raw signal into a ranked, actionable finding instead of a wall of alerts.
- The execution layer is your automation or runbook engine, the piece that actually takes action and includes hooks for verification and rollback.
- Integrations connect all of this to your ITSM platform for ticketing and audit trail, your identity provider (Entra or another IAM system) for access control, and cloud-native controls like Azure Automanage, which handles automated lifecycle management for Windows and Linux VMs, including drift detection, though Windows baselines can auto-remediate while Linux baselines are often audit-only today.
That last distinction matters more than it sounds. If your automation strategy assumes every platform behaves the same way, you'll find the gap the hard way, usually during an incident rather than in a planning meeting. Vendor openness, meaning real APIs and telemetry export rather than a closed dashboard, is what lets these layers actually integrate instead of sitting next to each other unconnected.
A Staged Rollout Plan That Won't Blow Up Your Environment
The order you tackle this in matters as much as the technology you pick. Move too fast and you'll automate a bad decision before you've built the trust to catch it.
- Pick a pilot that's high-volume and low-risk. Certificate expiry remediation, disk cleanup, or restart-on-crash for a non-critical service are common starting points because a mistake here is annoying, not catastrophic.
- Close the visibility gaps. You need accurate telemetry and a service map before you automate anything. Practitioners consistently report that data quality and service mapping are the hardest part of the whole effort, not the automation logic itself. Know what's running, what state it's in, and what depends on it.
- Write the policy before you write the runbook. Define your SLOs, cost caps, and exactly which actions get pre-approved. This is also where you set your approval gates.
- Stage the execution. Start with recommendations only, move to human-approved actions, then graduate to auto-run with rollback once you trust the pattern.
- Measure, refine, expand. Use the baseline metrics from your pilot to justify the next automation candidate, and adjust your policies based on what actually happened, not what you assumed would happen.
Pro Tip: Resist the urge to pilot on your most painful incident type first. Painful usually means high-stakes and poorly understood, which is exactly the combination that makes a first pilot risky. Save the hard problem for stage three of the ladder, once your team trusts the process.
If you're piloting on infrastructure that lives in Azure, a practical runbook automation approach for SMBs is worth reviewing before you write your first policy, since the staging and rollback patterns translate directly.
Governance Isn't Optional at Any Stage of Autonomy
Every autonomous action needs a policy boundary that defines what it's allowed to do and an approval threshold for anything outside that boundary. Skip this step and you don't have autonomous IT, you have unsupervised scripts with a machine learning label attached.
The minimum controls worth building in from day one:
- Role-based access control (RBAC) so only authorized policies can trigger high-impact actions
- Audit logging that creates tamper-resistant evidence of what ran, when, and why
- Staging environments for testing every runbook before it touches production, with mandatory verification and rollback steps built in
- Ongoing monitoring for agent behavior and model drift, because a policy that was safe six months ago may not be safe on today's infrastructure
Agentic AI raises the stakes here specifically. When multiple agents can act independently across your environment, discovery and governance tooling become critical to avoid one agent's action creating a side effect another agent misinterprets. If you're running or planning to run agent-based automation, an agent monitoring approach built for production is worth setting up before you scale past your pilot, not after something breaks.
How Mindpodtech Approaches Autonomous IT in Practice
Mindpodtech builds autonomous IT operations the way this article just laid out: staged, measured, and governed from the first pilot. The advisory work spans fractional technology leadership, agentic AI strategy and governance, cloud architecture and cost optimization, security assessment, disaster recovery, and custom software, that means the governance conversation and the automation build happen with the same team instead of getting handed off between vendors.
For teams that want the closed loop already built rather than assembled from scratch, MITB integrates Microsoft, Entra, Azure, and MSP support into a single autonomous operations layer, aimed specifically at the Microsoft-centric environments most SMBs and mid-market companies actually run.
The engagement model matches the maturity ladder covered earlier:
- A free technology assessment that maps your current telemetry, gaps, and risk before anything gets automated
- A prioritized, plain-language plan the client owns outright, not a locked-in roadmap tied to one vendor's tooling
- Delivery and ongoing operation of the pilot, tracked against the same metrics discussed above: uptime, MTTR, and cost per incident
A typical pilot doesn't promise a specific percentage improvement on day one. It promises a measured baseline, a staged rollout, and a policy framework you can audit.
An Implementer's Take on What Actually Slows Teams Down
The tradeoff nobody wants to say out loud is that speed and control pull against each other, and every team eventually has to pick a side of that line for each specific action. Governance isn't the boring part you add after the automation works. It's the part that decides whether the automation is trustworthy at all.
If you're evaluating this for your own environment, don't start with the most ambitious use case on your list. Start with one pilot, one clearly defined SLO, and a rollback path you've actually tested in staging. Everything else, including the agentic AI hype cycle, can wait until that first loop proves itself. If you want a second opinion on where your environment stands before committing to a build, that's a conversation worth having early rather than after the first automated action goes sideways.
— jaras
Start With a Free Assessment, Not a Full Rebuild
You don't need to rip out your current stack to get to autonomous IT operations. What you need is an honest read on where your telemetry has gaps, which incidents are actually safe to automate first, and a policy framework that won't let a runbook run wild. Mindpodtech's free technology assessment is built around exactly that question, and it produces a prioritized plan you own, not a sales deck.

If your environment is Microsoft-centric, MITB is worth a direct look, since it's purpose-built for autonomous operations across Microsoft, Entra, and Azure rather than a general-purpose platform retrofitted for it. And if certificate expiry or uptime monitoring is on your shortlist for a first pilot, pairing that automation with dedicated certificate and uptime monitoring closes a gap most teams don't catch until it's already an outage. Book the assessment, get the plan, and decide from there whether a pilot makes sense for your team this quarter.
Sources
For readers who want to go deeper on the technical foundations behind this article: Azure Automanage documents concrete cloud automation behavior and its current limits. Cisco's AIOps explainer covers the ML layer underneath the decision engine. LogicMonitor's autonomous IT overview and Tanium's piece on scaling autonomous operations both address the governance and visibility prerequisites covered above.
- What is AIOps? — Cisco
- Autonomous IT — LogicMonitor
- Autonomous IT operations: Transforming enterprise IT management — Tanium
FAQ
What Is the Difference Between Automation and Autonomous IT?
Automation runs a fixed script on trigger. Autonomous IT connects detection, decision, action, and verification into a closed loop governed by policy, so the system adapts its response rather than following one static path.
How Long Does It Take to Launch a First Autonomous IT Pilot?
Timelines vary by environment, but most teams spend two to four weeks establishing a telemetry baseline before automating anything, then run the pilot itself for several weeks to gather comparable metrics.
Is Autonomous IT Safe for Small and Mid-Market Companies?
Yes, when it starts with a low-risk, high-volume use case and includes RBAC, audit logging, and rollback from day one. Mindpodtech's engagement model builds these guardrails into every pilot before scaling further.
What Metrics Prove an Autonomous IT Pilot Is Working?
Mean time to detect, mean time to resolve, alert noise volume, and service availability against your existing SLOs are the four metrics worth tracking against your own pre-pilot baseline.
Do I Need AIOps Before I Can Automate IT Operations?
Not for every use case, but AIOps becomes valuable once you have enough telemetry volume that manual correlation is slowing your team down, since it automates the pattern recognition a human would otherwise do by hand.